
ARC GAUNTLET
Test the policy.
Compare the results.
Evaluate robot policies with repeatable tests. Compare each candidate with a previous version, measure task success and recovery, and catch regressions before deployment.
AUTONA ROBOT CLOUD / POLICY TESTING & BENCHMARKS
- START WITH
- Policy candidates, test scenarios, baseline results
- WORK TOWARD
- Benchmark comparisons, failure reports, and release evidence
- BUILT FOR
- Robot-learning and release teams
Compare policies. See what changed.
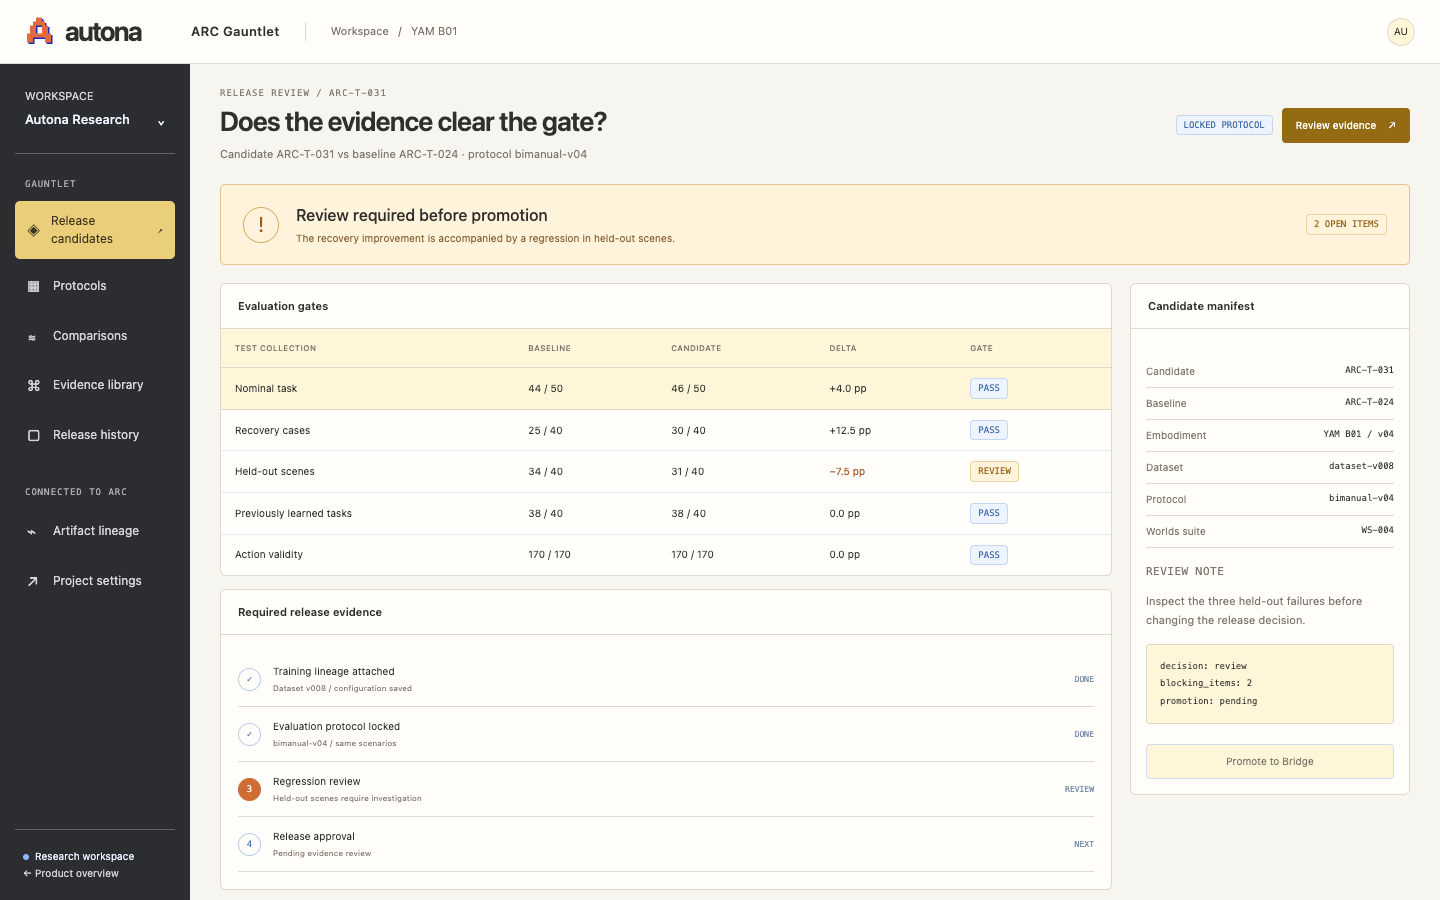
Compare candidate and baseline task results, inspect failed cases, and see which release criteria are met.
Did the update
make the robot better?
ARC Worlds runs policies in simulation. Gauntlet compares the resulting task outcomes against a baseline and explicit thresholds, showing what improved, what regressed, and what needs another test.
Define the benchmark
Choose the task scenarios, success criteria, and previous policy version to compare against. Keep the conditions consistent across candidates.
Compare policy versions
Use recorded runs from ARC Worlds to compare task success, recovery, unfamiliar scenes, and previously learned skills. Inspect the failures behind each score.
Record the result
Record whether the candidate meets the release criteria, with its comparisons and failure reports. Carry that evidence with the model into Bridge.
Put your policy to the test.
Tell us about your robot, your team, and the problem you want to solve.